Generic conversational AI models are exceptional at general reasoning, language translation, and drafting broad text. However, when asked about specific company policies, personal research notes, proprietary product manuals, or specialized internal workflows, standard models frequently hallucinate or provide vague answers. By grounding an AI assistant in your own private document library, you create a dedicated domain expert that answers queries with exact, cited references.
Understanding Retrieval-Augmented Generation (RAG)
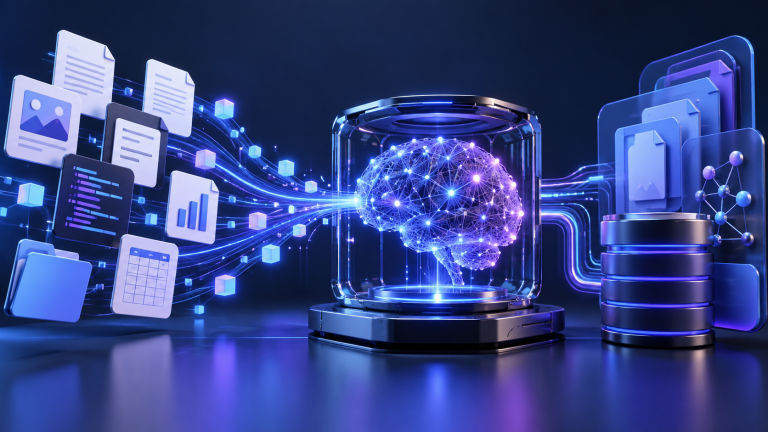
Rather than attempting to fine-tune a multi-billion parameter model—a process that requires immense computational expense and GPU memory—modern custom assistants leverage Retrieval-Augmented Generation (RAG). The architecture works in three sequential phases:
- Document Chunking & Vectorization: Your text files (PDFs, Markdown, DOCX) are split into semantic paragraphs and converted into mathematical vector embeddings.
- Similarity Search: When a user asks a question, the system queries a vector database to retrieve the top 3–5 most relevant paragraphs from your documentation.
- Grounded Generation: The retrieved reference excerpts are passed into the LLM’s prompt window as context, instructing the model to generate its response exclusively from the supplied facts.
Method 1: Creating a Custom GPT in OpenAI ChatGPT Plus/Team
For non-programmers, OpenAI’s GPT Builder provides the fastest visual path to deploying a custom assistant:
- Navigate to Explore GPTs and click Create.
- In the Configure tab, provide a descriptive title and concise role instructions (e.g., “You are an enterprise technical support specialist assisting employees with Windows 11 and company VPN configurations”).
- Under Knowledge, upload your clean reference documents. Ensure files are formatted in clear text (clean PDFs or Markdown files without complex image tables provide the highest retrieval accuracy).
- Configure Capabilities: Enable Web Browsing and Code Interpreter only if your specific workflow demands live calculations or file analysis.
Method 2: Building a Private, Local RAG Assistant with AnythingLLM
For organizations and individuals handling confidential customer data or proprietary research, uploading documents to external commercial clouds is unacceptable. The open-source AnythingLLM application enables 100% local, offline RAG on your desktop:
- Download and install AnythingLLM for Windows, macOS, or Linux.
- Connect your preferred local inference engine (such as Ollama running
llama3.1ormistral). - Select an embedded local vector database (such as LanceDB) which runs entirely in system memory.
- Create a new “Workspace”, drag and drop your private PDFs and text documents, and click “Embed”.
Once embedded, you can chat with your private documents entirely offline with zero data packets leaving your machine.
Best Practices for Preparing Document Libraries
The accuracy of any customized AI assistant is governed directly by the quality of its source material:
- Remove Formatting Clutter: Strip headers, footers, page numbers, and repetitive copyright legal disclaimers from PDFs prior to ingestion.
- Use Descriptive Headers: Structure internal SOPs and technical notes with logical H1 and H2 tags so the vectorization engine segments topics accurately.
- Maintain Temporal Context: If procedures change over time, label documents with explicit version tags or dates (e.g.,
[Updated Sept 2026]) to prevent contradictory answers.